Research Blogs
Accessible project stories from my research internship at Tencent AI Lab. Click any card to explore the full blog.
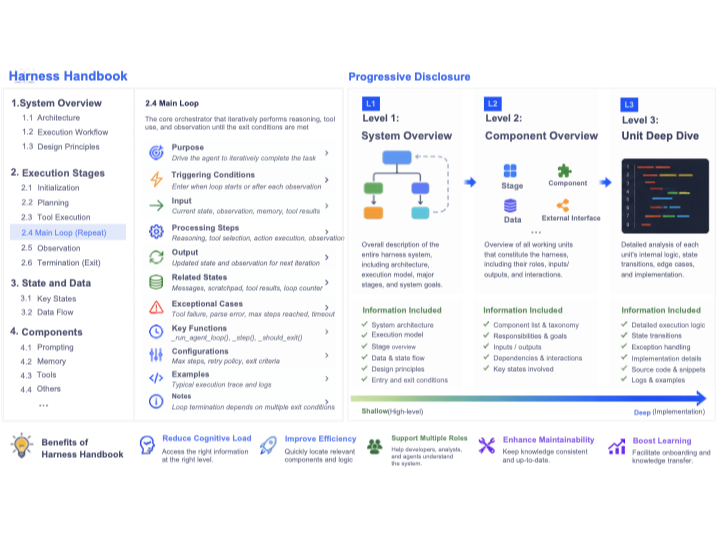
Harness Handbook
Making evolving agent harnesses readable, navigable, and editable
A behavior-centric map from high-level agent behavior to concrete implementation sites, designed for understanding, auditing, and modifying complex harnesses.
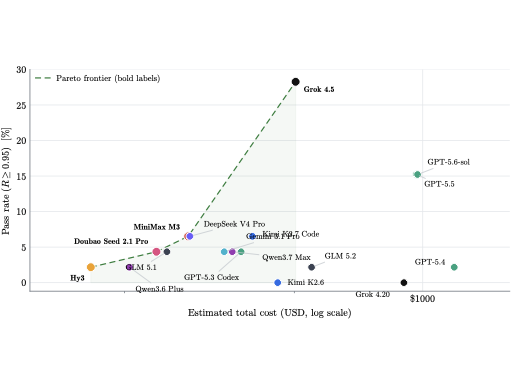
Long-Horizon Terminal-Bench
Where agents run out of steam
An interactive report on 46 long-horizon terminal tasks, dense process rewards, and what 18 frontier models reveal about sustained agent execution.
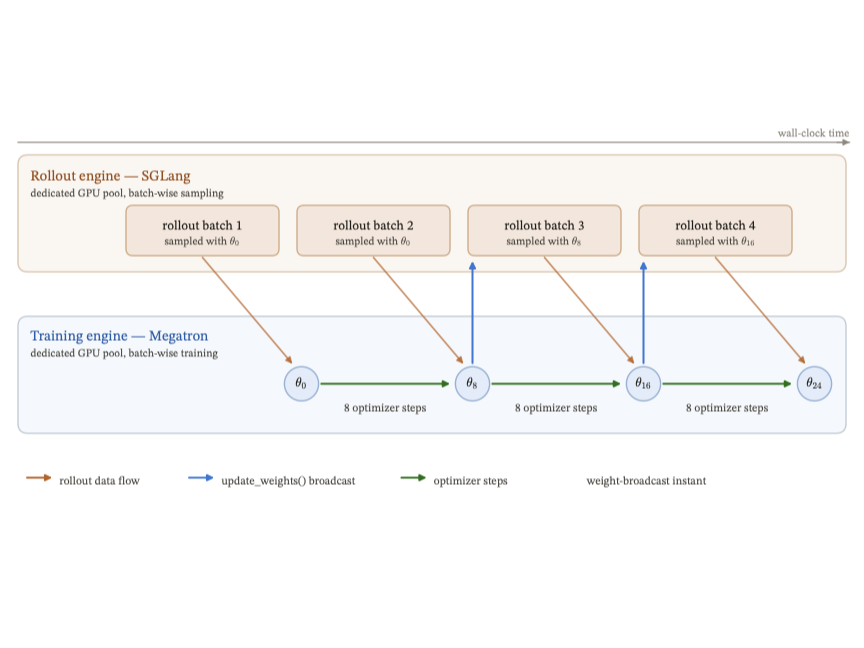
Stale but Stable
Staleness-adaptive trust regions for asynchronous reinforcement learning
A field guide to policy staleness in asynchronous LLM reinforcement learning and the SAT method for stabilizing high-mismatch updates.
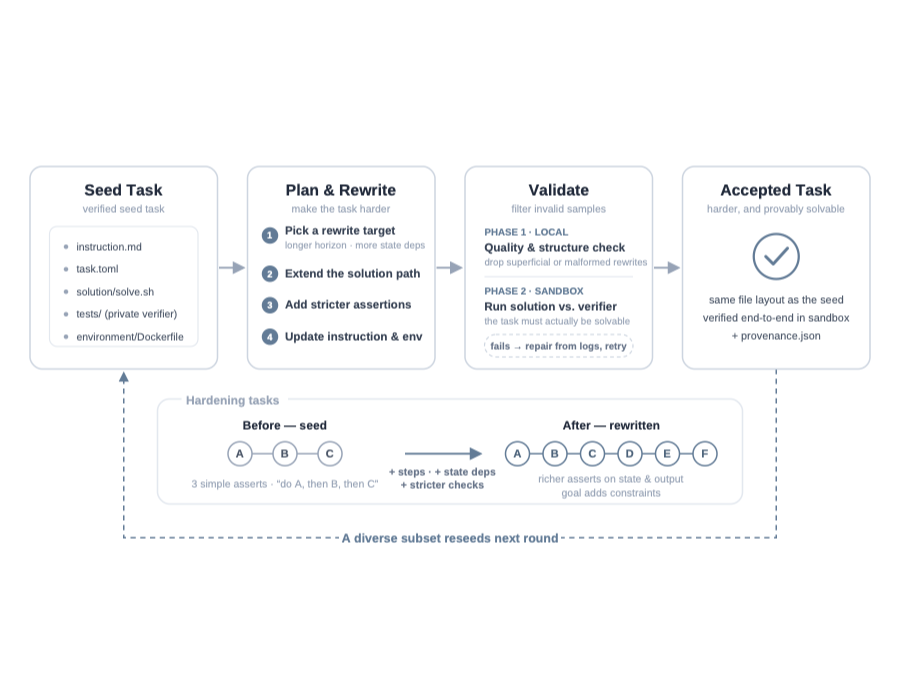
Recursive Synthesis
Synthesizing verified long-horizon terminal tasks at low cost
An interactive look at recursively generating 37,484 verified terminal-agent tasks and using them for supervised fine-tuning and reinforcement learning.