Publications
A collection of my research work.

More Memory, Worse Agents: Error Reproduction and Anti-Persistence in LLM Agents
Ruhan Wang, Kishan Panaganti, Dongruo Zhou
The Fortieth Conference on Neural Information Processing Systems (NeurIPS) 2026
Identifies a structural error-reproduction failure mode in persistent abstraction memory for self-improving LLM agents, and proposes ANTI-PERSISTENCE: a memory module that stores only factual interaction records and synthesizes task-specific abstractions on demand via an adaptive contextual UCB bandit over abstraction modes.
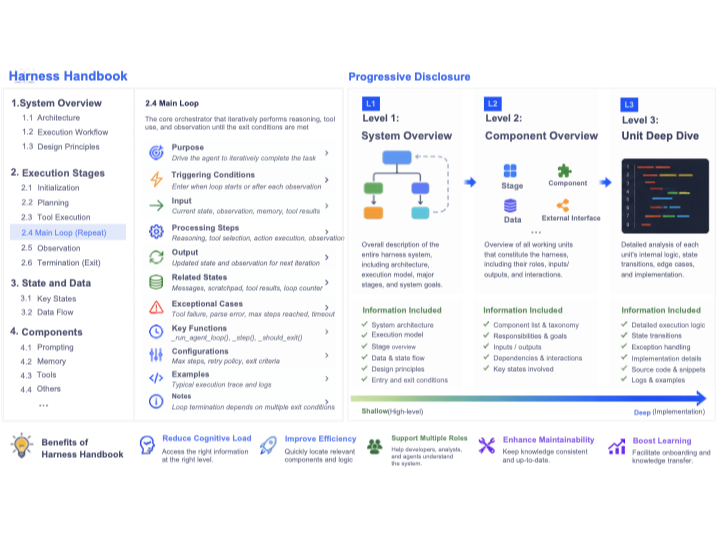
Harness Handbook: Making Evolving Agent Harnesses Readable, Navigable, and Editable
Ruhan Wang, Yucheng Shi, Zongxia Li, Zhongzhi Li, Yue Yu, Junyao Yang, Kishan Panaganti, Haitao Mi, Dongruo Zhou, Leowei Liang
arXiv preprint arXiv:2607.13285 2026
A behavior-centric representation that maps high-level agent-system behaviors to concrete implementation sites, making evolving harnesses easier to navigate, audit, and modify.
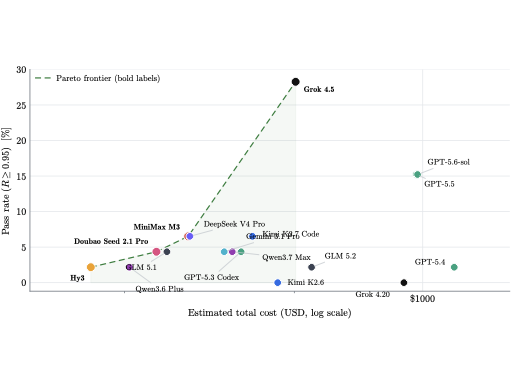
Long-Horizon-Terminal-Bench: Testing the Limits of Agents on Long-Horizon Terminal Tasks with Dense Reward-Based Grading
Zongxia Li, Zhongzhi Li, Yucheng Shi, Ruhan Wang, Junyao Yang, Zhichao Liu, Xiyang Wu, Anhao Li, Yue Yu, Ninghao Liu, Lichao Sun, Haotao Mi, Leowei Liang
arXiv preprint arXiv:2607.08964 2026
A benchmark of 46 long-horizon terminal tasks across nine categories with dense intermediate reward-based grading, evaluated on 15 frontier models.
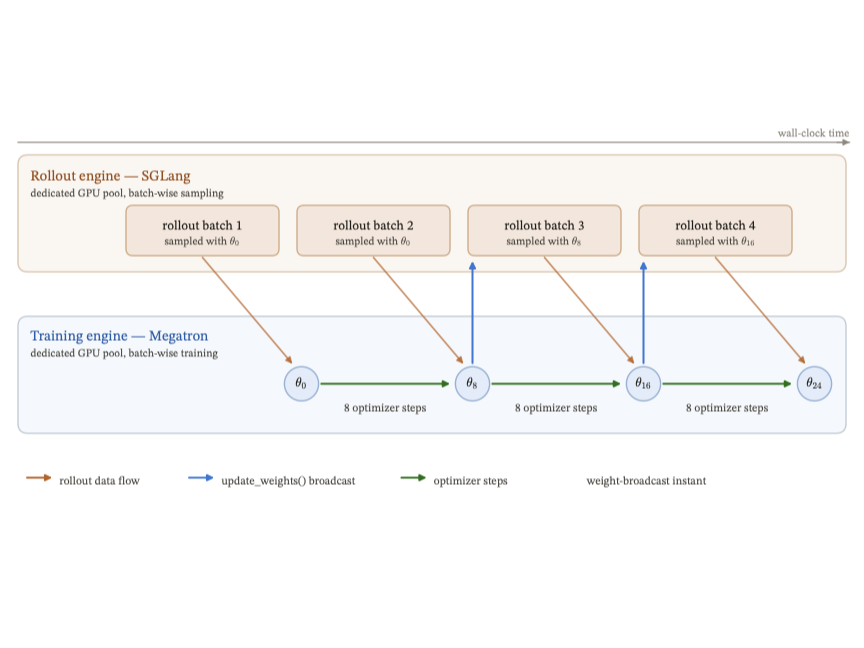
Stale but Stable: Staleness-Adaptive Trust Regions for Stabilizing Asynchronous Reinforcement Learning
Junyao Yang, Yucheng Shi, Zongxia Li, Zhongzhi Li, Ruhan Wang, Xiangxin Zhou, Kishan Panaganti, Haitao Mi, Leowei Liang
arXiv preprint arXiv:2607.18722 2026
A staleness-adaptive trust region that stabilizes fully asynchronous reinforcement learning by tightening policy updates where rollout-policy mismatch is highest.
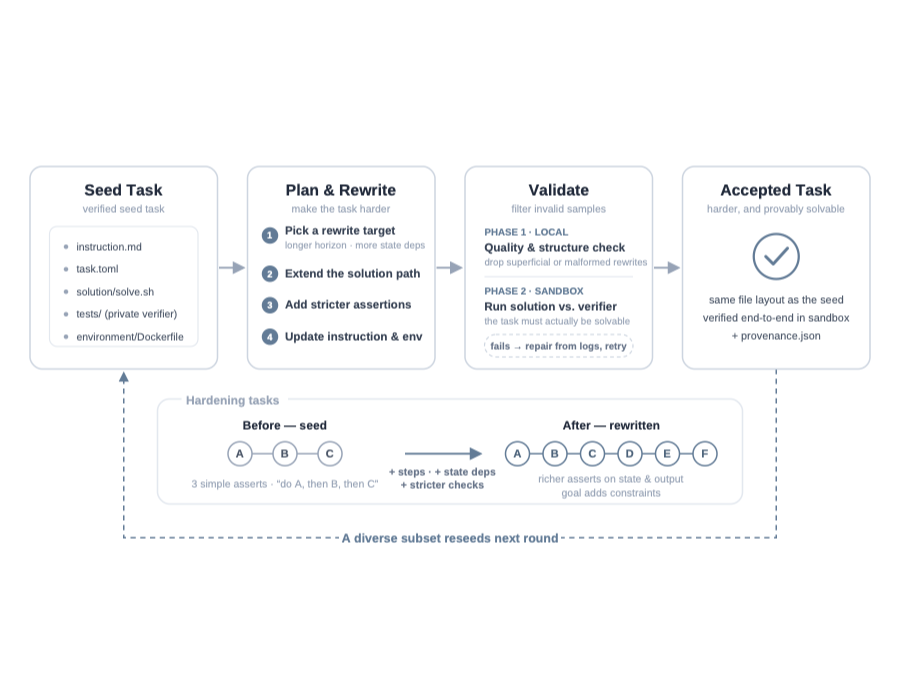
Recursive Synthesis for Long-Horizon Terminal Tasks
Zhongzhi Li, Yucheng Shi, Zongxia Li, Ruhan Wang, Anhao Li, Zixun Huang, Junyao Yang, Lei Ke, Ninghao Liu, Haitao Mi, Leowei Liang
arXiv preprint arXiv:2608.05466 2026
A recursive verified synthesis framework that produces 37,484 increasingly difficult long-horizon terminal-agent tasks across fifteen rounds.

FERA: Uncertainty-Aware Federated Reasoning for Large Language Models
Ruhan Wang, Chengkai Huang, Zhiyong Wang, Junda Wu, Rui Wang, Tong Yu, Julian McAuley, Lina Yao, Dongruo Zhou
Conference on Language Modeling (COLM) 2026
A parameter-free federated reasoning framework (FERA) using uncertainty quantification and a dual-pipeline aggregation mechanism for cross-client knowledge integration.

Instance-Dependent Continuous-Time Reinforcement Learning via Maximum Likelihood Estimation
Runze Zhao, Yue Yu, Ruhan Wang, Chunfeng Huang, Dongruo Zhou
Forty-Third International Conference on Machine Learning (ICML) 2026
Instance-dependent analysis of continuous-time reinforcement learning using maximum likelihood estimation.

Federated In-Context Learning: Iterative Refinement for Improved Answer Quality
Ruhan Wang, Zhiyong Wang, Chengkai Huang, Rui Wang, Tong Yu, Lina Yao, John C.S. Lui, Dongruo Zhou
Forty-Second International Conference on Machine Learning (ICML) 2025
Privacy-preserving framework (Fed-ICL) that combines federated learning with in-context learning to collaboratively train diverse LLM agents, with theoretical equivalence to established FL algorithms.

Towards Agentic Recommender Systems in the Era of Multimodal Large Language Models
Chengkai Huang, Junda Wu, Yu Xia, Sheldon Yu, Ruhan Wang, Tong Yu, Ruiyi Zhang, Ryan Rossi, Branislav Kveton, Dongruo Zhou, Julian McAuley, Lina Yao
ACM Transactions on Intelligent Systems and Technology (TIST) 2025
Formal framework for LLM-based Agentic Recommender Systems (LLM-ARS) covering user profiling, memory, planning, and action selection, with seven key research challenges identified.


Quantum Diffusion Models for Few-Shot Learning
Ruhan Wang, Ye Wang, Jing Liu, Toshiaki Koike-Akino
2025 IEEE International Conference on AI and Data Analytics (ICAD) 2025
Quantum diffusion model framework for few-shot learning, combining generative quantum circuits with classical diffusion training.

Safe Decision Transformer with Learning-based Constraints
Ruhan Wang, Dongruo Zhou
7th Annual Learning for Dynamics and Control Conference (L4DC) 2025
Constrained Q-learning Decision Transformer (CQDT) for safe offline RL, addressing stitching limitations of CDT while strictly adhering to safety constraints.

Return Augmented Decision Transformer for Off-Dynamics Reinforcement Learning
Ruhan Wang, Yu Yang, Zhishuai Liu, Dongruo Zhou, Pan Xu
Transactions on Machine Learning Research (TMLR) 2024
Return Augmented Decision Transformer (RADT) for offline off-dynamics RL with rigorous suboptimality analysis and D4RL evaluation across off-dynamics shifts.

LLMCarbon: Modeling the End-to-End Carbon Footprint of Large Language Models
Ahmad Faiz, Sotaro Kaneda, Ruhan Wang, Rita Osi, Parteek Sharma, Fan Chen, Lei Jiang
The Twelfth International Conference on Learning Representations (ICLR) 2024
End-to-end carbon footprint projection model for LLMs across training, inference, experimentation, and storage phases, integrating LLM, hardware, and data center parameters.

JustQ: Automated Deployment of Fair and Accurate Quantum Neural Networks
Ruhan Wang, Lei Jiang, Fahiz Baba-Yara, Fan Chen
29th Asia and South Pacific Design Automation Conference (ASP-DAC) 2024
First fairness-aware QNN deployment framework jointly optimizing fairness and accuracy on NISQ devices via reinforcement-learning-driven design space exploration.

A Hybrid Quantum-Classical Neural Network for Learning Transferable Visual Representation
Ruhan Wang, Phil Richerme, Fan Chen
Quantum Science and Technology 2023
QCLIP, a hybrid quantum-classical architecture for learning transferable visual representations via Quantum Contrastive Language-Image Pre-training.
Person Re-Identification Based on Generative Adversarial Network and Self-Calibrated Convolution
Kaifang Li, Guancheng Hui, Ruhan Wang, Miaohui Zhang
Laser & Optoelectronics Progress 2022
Person re-identification framework combining GAN-based augmentation with self-calibrated convolution.
A Brief Analysis on Damaged Building Classification: Optimizer and Learning Rate
Ruhan Wang, Ruixin Qiao, Yukang Zou
2022 International Conference on Cloud Computing, Performance Computing and Deep Learning (SPIE 12287) 2022
Empirical comparison of optimizer and learning-rate schedule combinations for ResNet-based post-hurricane damaged building classification on satellite imagery.